Scoring
One to four, and a target you can keep.
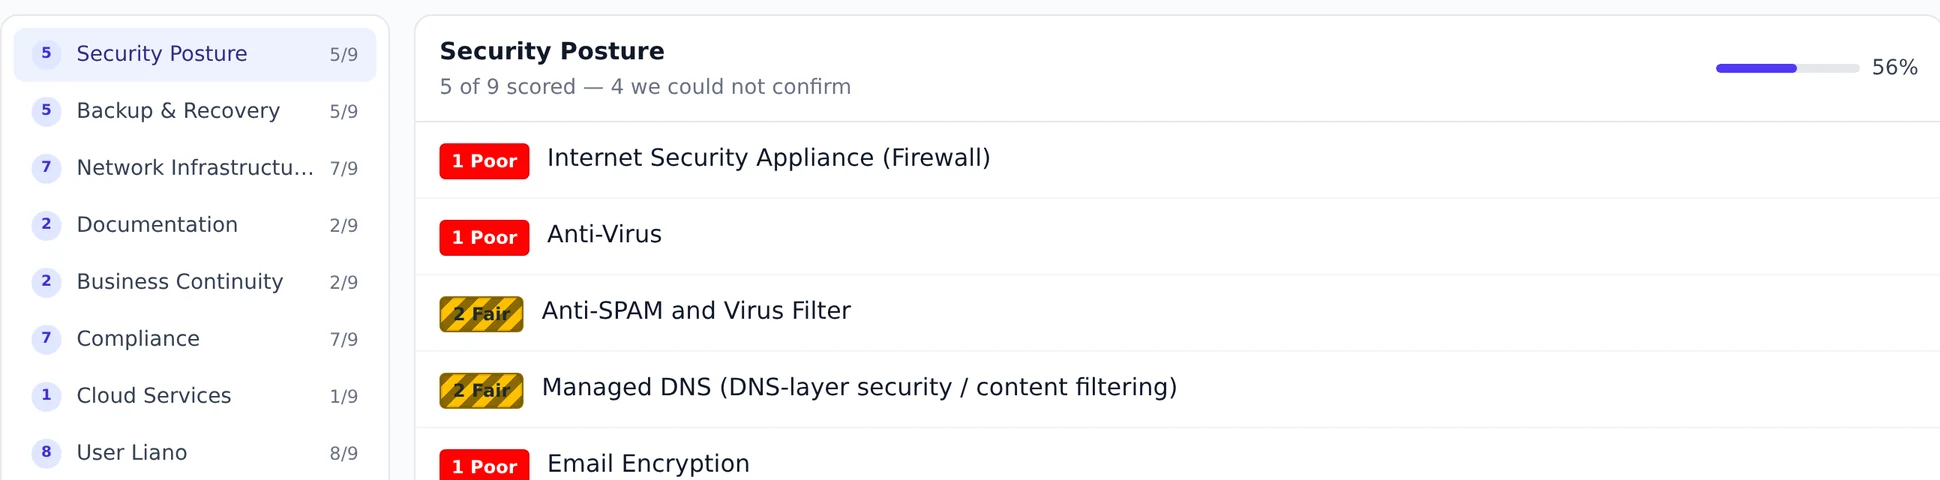
Every item in the assessment is rated Poor, Fair, Good or Excellent, and the 90-day goal that goes on the deck is derived from that rating by a fixed mapping. The mapping is not configurable, and that is the point: a goal score is a promise made to a customer in a room, and a tunable target is how those promises stop meaning anything.
How it works
From a rating to a promise
Three properties of the deriver, and the third is the one that matters most on a signed deck.
Poor and Fair both go to Good
The destination is the same; only the amount of work differs. Promising that an actively harmful gap will be merely present but incomplete in 90 days is not a proposal anybody signs.
Good goes to Excellent
The remaining step is documentation, monitoring and verification. Excellent stays Excellent – a target below the current rating is not a target.
And an unscored item gets nothing
A rating outside the scale returns no goal at all. The alternative is a fabricated target on a row nobody has looked at, which is exactly the failure the whole approach exists to avoid. The item stays in the denominator that was stamped when the assessment was built, so the coverage figure is honest about what was skipped rather than quietly shrinking to match what got done.
In the product
The ratings, section by section.
Who it is for
For the person who has to deliver the 90 days
The engineer who inherits the remediation plan is the one who finds out whether the target was honest. Deriving it from a fixed rule is how the deck and the delivery stay the same conversation.
- Technicians scoring an estate they will have to fix
- Owners who would rather under-promise on a signed roadmap
- Anyone who has been handed a plan built to sound good
Questions
The things people actually ask.
Can I override a derived goal?
Yes, and once you do the deriver never overwrites you. A goal a person set by hand is a promise a person made, and the system treats it as more authoritative than its own mapping rather than less.
Why is the mapping fixed?
Because a configurable one lets a target be tuned per deal, which is the same failure as letting a model write it – the number stops describing the work and starts describing what would close. A rep who disagrees with a derived goal sets it by hand, which is visible; a tuned global rule is not.
Does AI do the scoring?
Only if you have turned AI autofill on, which is a second switch underneath the module switch and also defaults to off. Even then the model is prohibited from writing a goal score at all – it describes what is, and the promise stays derived or human.
What if an item does not apply to this client?
Leave it unscored. It stays in the frozen denominator, so the coverage figure is honest about what was not looked at, and it gets no derived target. IT Audit is a Marketplace add-on, so none of this runs in a workspace that has not installed it.
How do scores roll up, and does a single bad item get lost in an average?
Section scores roll up from the items inside them and the assessment score rolls up from the sections, so a reader can move between the headline and the row that produced it. Critical items are tracked separately from the rollup for exactly the reason you would expect – a single unbacked-up server averaged against nine healthy items reads as a good section, and that is the one row the customer needs to see.
Can I compare this audit against the last one?
Yes, item by item. A reassessment inherits the same template as the audit it follows, which is what makes the comparison a genuine before-and-after rather than a join across two differently shaped documents. Items the library gained or lost since then are reported as added or removed rather than being quietly folded into a movement figure.
Check a derived goal against your own delivery.
Take an estate you know and see whether the 90-day targets are ones your team would actually sign up to.